Ollama Deletes Your Task and Says 200: Don't Judge Qwen 3.8 27B by It
I replayed a coding agent through Ollama: when the window fills, Qwen 3.8 27B loses your task and the response still says 200. So I'd use llama-server instead.
A small software house posted on r/LocalLLM that Qwen 3.8 27B on an RTX 3090 is "practically unusable" for coding: it loops and ignores instructions. The top reply was "I can already tell you're running ollama", and they were. Plenty of people said Ollama silently truncates, but nobody I read said what it cuts, so I replayed an agent run through it.
When the context window fills, your system prompt and tools survive, your task gets deleted, and the response still says HTTP 200. So I wouldn't judge this model through Ollama. A better setup won't make a 27B into Claude Sonnet 5.5, but a bad run will finally tell you something about the model.
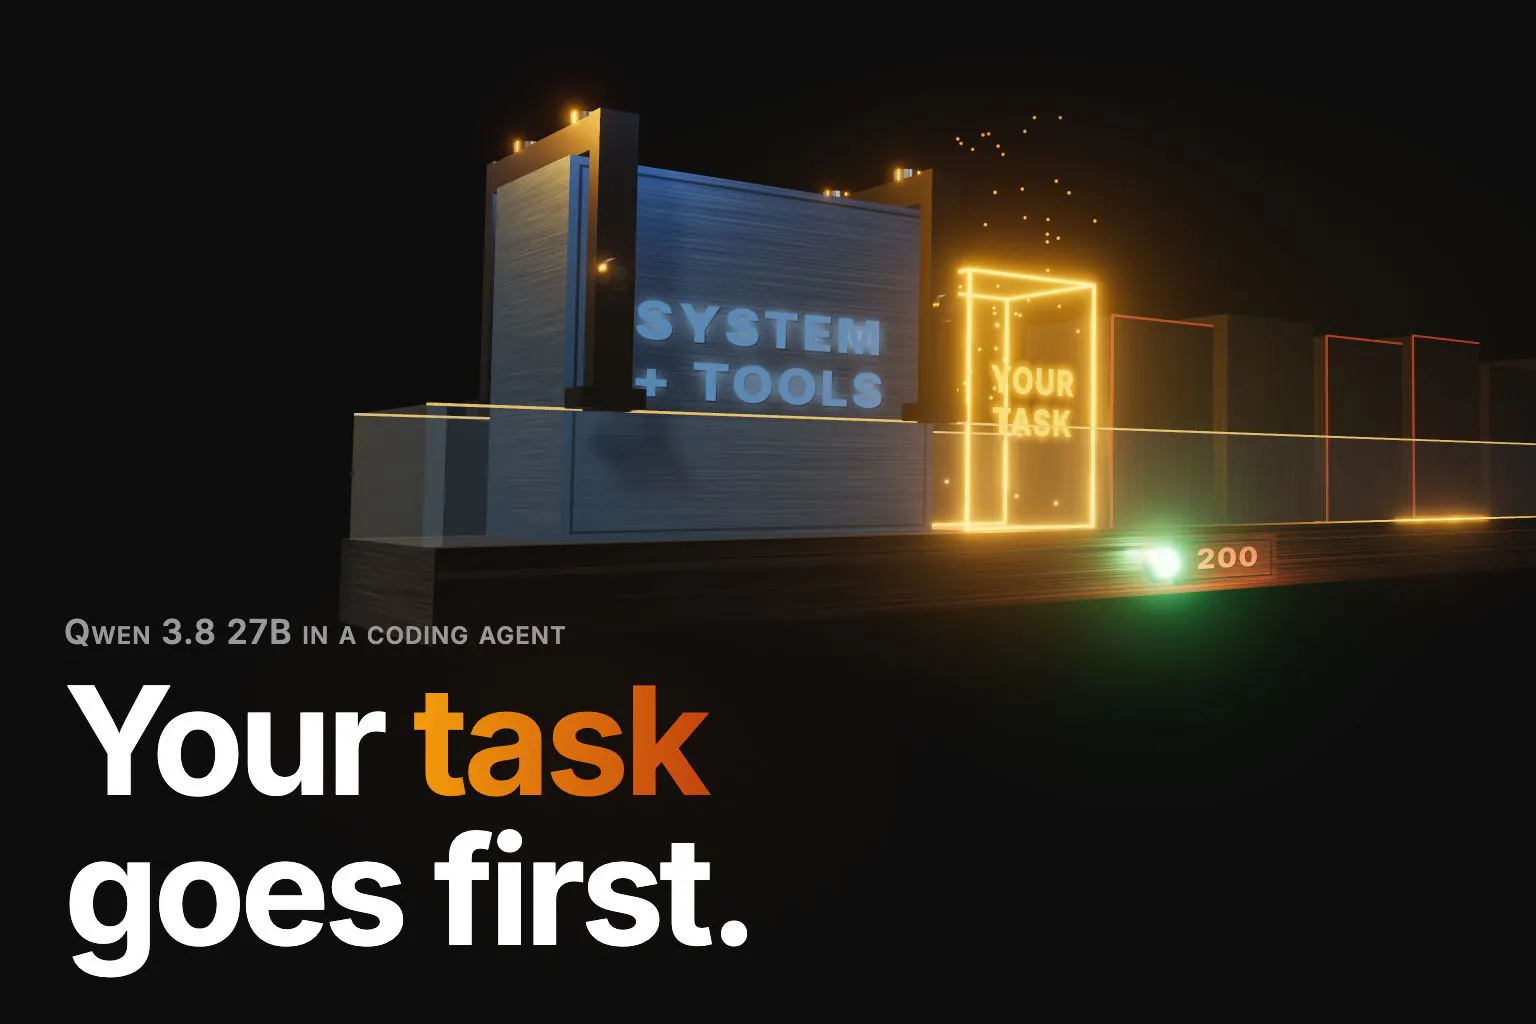
What Ollama deletes when the window fills
I ran Ollama with its real Qwen 3.8 renderer and tiny stand-in weights, since trimming only counts tokens. As of November 2026, its trim loop keeps system messages and tools, then drops the oldest other message until the prompt fits. That's your task, and on a 32K window, with message sizes I assumed, it went at step 7. The amber block is your task.
A model that knows its tools but not its job rereads files and loses those too. That's my guess, and it fits the thread's loops.
A bigger window only buys time, and I can't tell if the poster got their 128K or Ollama's default for a 24 GB card. Here are both at the same pace.
But an agent can't retry what it can't see
Another thread calls this model "sometimes so smart it scares me". But that's one good decision with you watching. An agent makes fifty in a row, so small errors multiply, and what saves a run is whether it can see them. A failing test gets retried, but a deleted message shows up nowhere.
So I'd run Qwen 3.8 27B on llama-server, which fails out loud
llama-server, the server in llama.cpp, refuses a prompt that's too big, and pi, a lightweight coding agent, knows what that refusal means. Compare what each reply gives an agent to work with.
Here's what I'd run: Q4 weights and an 8-bit KV cache, the model's running memory of every token, because at 128K a full-precision cache runs just past a 24 GB card by my arithmetic. I checked the flags against the docs, but I haven't run this on a 3090 or with Qwen's real weights.
llama-server -hf unsloth/Qwen3.8-27B-GGUF:UD-Q4_K_M \
  -c 131072 -ngl all -np 1 \
  --cache-type-k q8_0 --cache-type-v q8_0 --flash-attn on \
  --no-mmproj-offload --jinja
But some people on lightweight agents still see thought spirals once context loads up, and I have no test showing this setup stops that. Most of that thread argues about how smart a 27B is, and I can't settle it. I'd just want to see this model fail with its task still in the prompt before I took a side.
More from the Blog
NVIDIA MotionBricks: The 15,000 fps Isn't the News
MotionBricks' 15,000 fps is mostly a counting choice. I ran it on a laptop. The news is fast, smooth and accurate at once, enough to replace game transitions.
ChatGPT Images 2.6 GIFs Act Like Sprite Sheets: They Keep the Look, Lose Count
ChatGPT Images 2.6 GIFs behave like one sprite sheet cut into frames, so they keep the look and lose count. In 18 juggler runs, none kept three balls.