How do LLMs work? One loop explains almost everything they do
How do LLMs work? They predict one token, append it and repeat. Real probabilities from a real model show how that loop explains chat, tools and hallucination.
Guides, comparisons, and strategies for builders who ship.

How do LLMs work? They predict one token, append it and repeat. Real probabilities from a real model show how that loop explains chat, tools and hallucination.

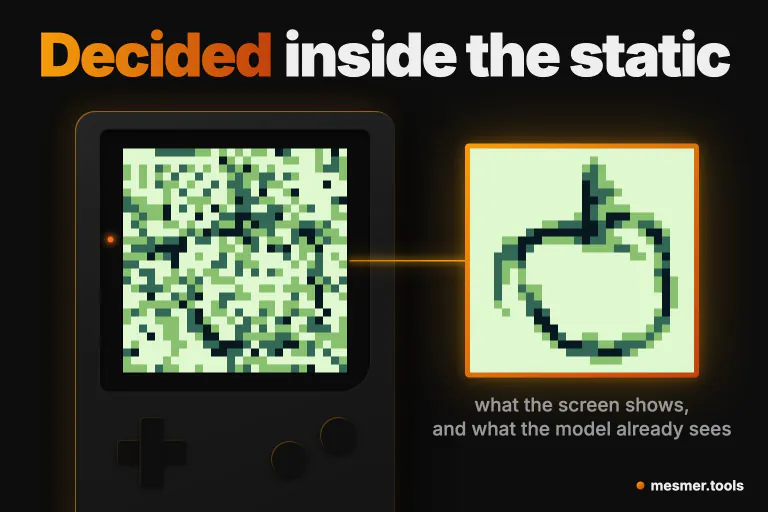
I changed a Game Boy diffusion model's subject mid-drawing. By step 6 of 16 the new request only ties the old one, and the canvas is still 83% noise.

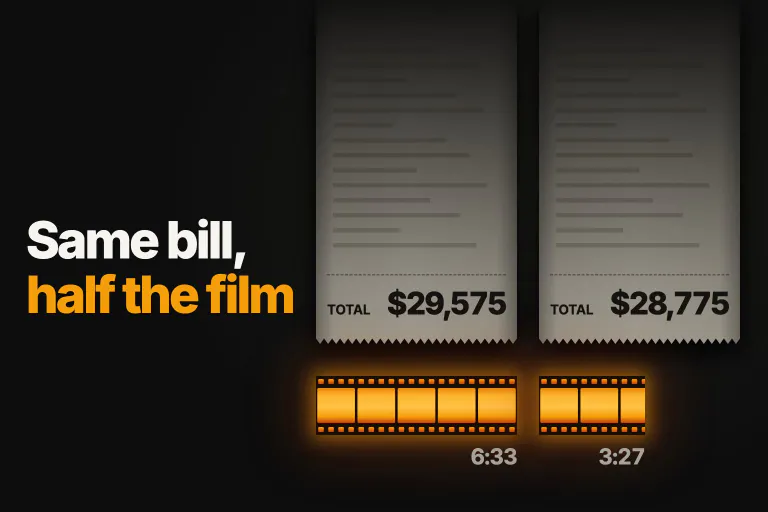
This Seedance AI film cost $28,775, about what a film nearly twice as long cost. The team got better at retries, but the episode bill didn't shrink.

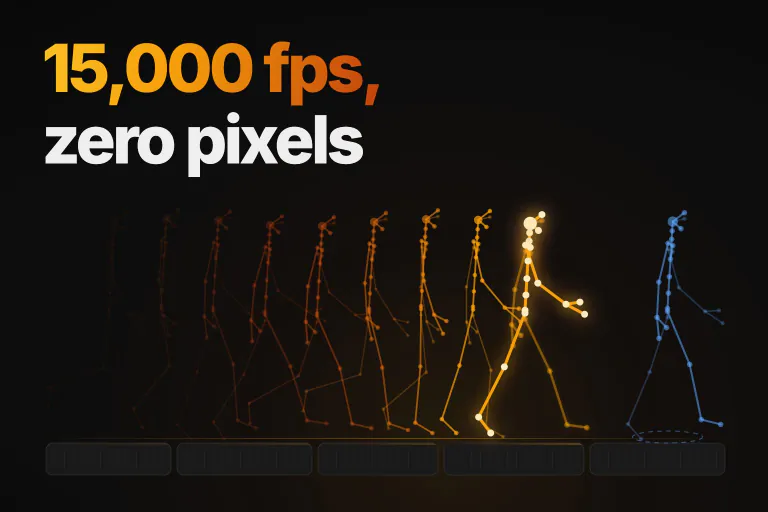
MotionBricks' 15,000 fps is mostly a counting choice. I ran it on a laptop. The news is fast, smooth and accurate at once, enough to replace game transitions.

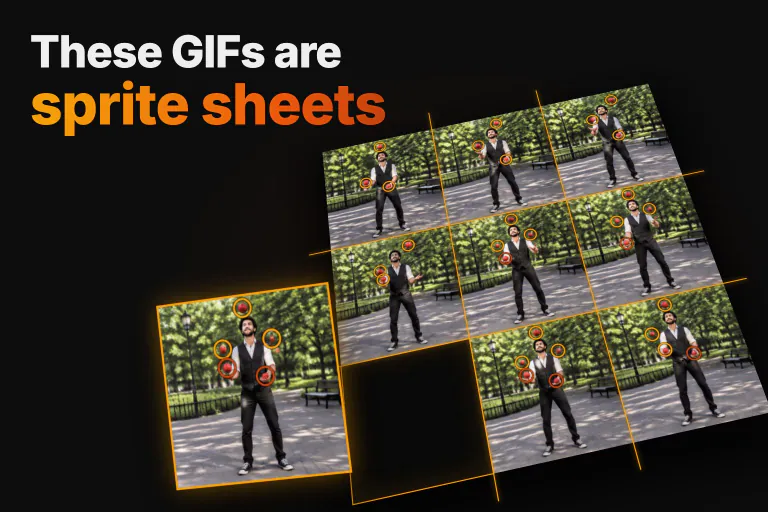
ChatGPT Images 2.6 GIFs behave like one sprite sheet cut into frames, so they keep the look and lose count. In 18 juggler runs, none kept three balls.

I ran 29 songs through three AI music detectors you can download. The best caught every Suno song and no human ones, but passed 8 of 10 ACE-Step songs as human.

OpenAI and Anthropic say their AI models refuted the Exponential Time Hypothesis. I believe the proof, but its speedup starts past 10^10,000 variables.

Black October's bug count was more noise than danger. The scary part: AI made exploits cheap to prove, so a PHP bug shelved for six years rooted firewalls.
A 3090 owner posted 1.9x, then 10% on his real job. The BF16 patch doubles one kind of math: images gain 26-59%, chat nothing, and a free setting can beat it.

Higgsfield's letter to ComfyUI goes after a name, not the apps. In one open rebuild, 72 of 120 apps are one prompt, and a swap costs $2.21 or 32 minutes.

A KV cache is a model's working memory for one response. Prompt caching keeps it between requests: why it's cheap, why it expires, why long chats cost more.

A YouTuber found a camera from plane tones nobody could hear. I tried it: it matched his spot, then named a place 99 km off once I deleted the right planes.

Two thirds of local LLM downloads trace to Alibaba, which uploaded almost none of them. Qwen's pledge names versions, but the license is what to watch.

DeepSeek V4.1 Flash is cheap because an agent's re-reads come off nearly free disk. A modeled week costs 72 cents against $44 on Opus, and the price can last.

In ComfyUI, MiniMax H3 cards from 8 to 32 GB hit a 10x slowdown at about the same clip size. Memory nodes move it further, so change nodes before you buy VRAM.

Udio switched off downloads and Suno now rations them. I ran five prompts through six Suno alternatives and compared the terms, price and lyric accuracy.

I ran 85 Heretic-style abliteration edits on a small model and quizzed each: refusals come out almost free, but the damage score only warns at the extremes.

GPT-6 Astra took Qwen from 7.9% to 48.1% on MATH-500 by editing 0.016% of its model weights. MIT's logs show it fixed a loop and added no new math.

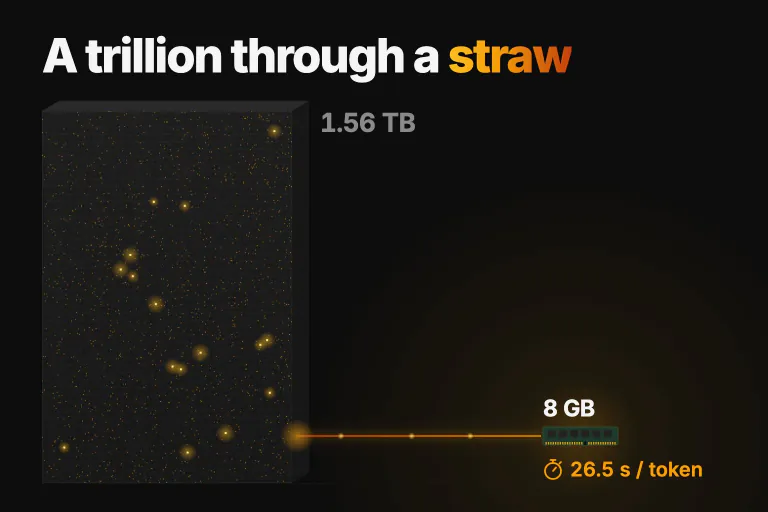
Kimi K3 really runs under an 8 GB cap, but every token reads 135 GB, so a long reply takes most of a day. Why that happens, and what I'd do instead.

I replayed a coding agent through Ollama: when the window fills, Qwen 3.8 27B loses your task and the response still says 200. So I'd use llama-server instead.

I asked 13 current LLMs 40 edgy but legitimate questions. Most refused none. Where refusals remain, and when an uncensored LLM is actually worth it.

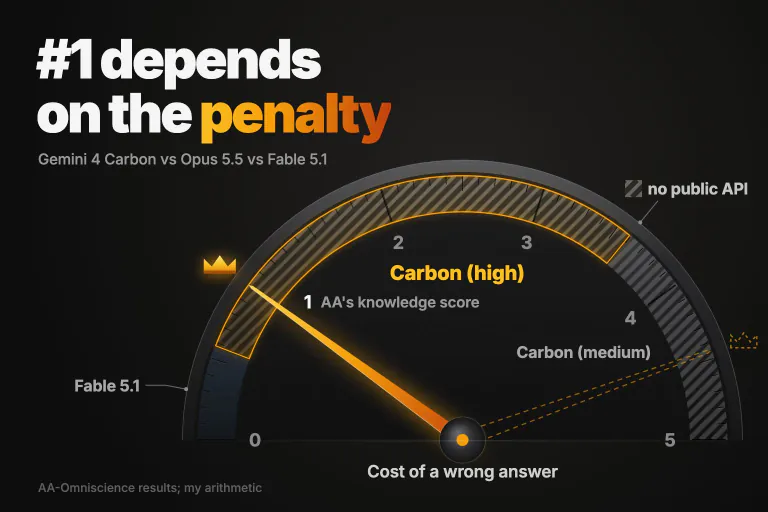
Gemini 4 Carbon tops the AI index by about a point, and a 5% term that pays for saying "I don't know" decides it. So pick by what a mistake costs you.

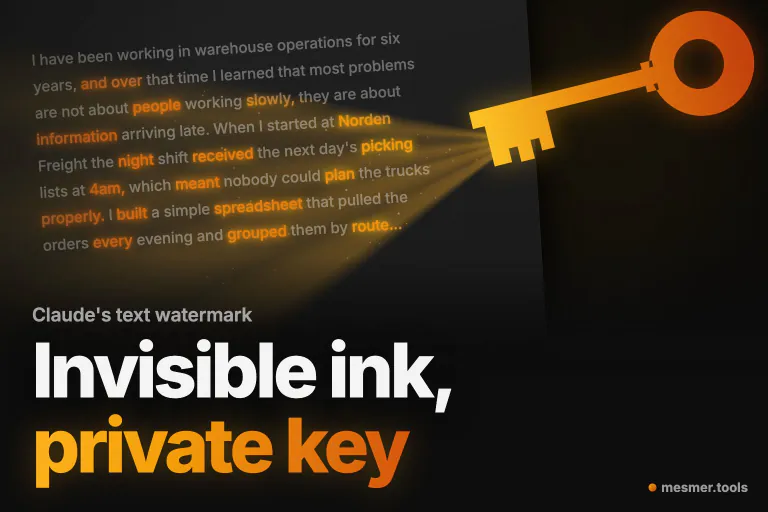
Claude hides a watermark in its word choices. I built the design: a rewrite of your own words looks generated, and a paraphraser scrubs the mark away.

Reverse engineering a smart TV can trip Claude's safeguard, but you don't need it: in a 2024 test, ad settings alone stopped ACR traffic. Here's where they are.

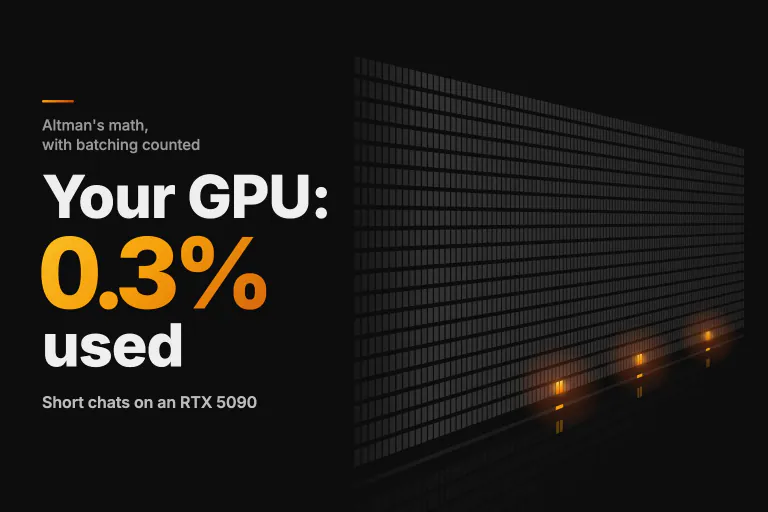
Sam Altman says local inference wastes DRAM. He's right, and on short chats he undersold it, but every RTX 5090 on Earth is two or three days of Nvidia's racks.

What --dangerously-skip-permissions changes in Claude Code and Codex, tested on a booby-trapped repo, plus a devcontainer that closes the network.

The best realistic AI image generator costs about 4 cents: GPT Image 2.5 on high and Nano Banana 2.1 passed 11 of 12 photo tests. Max only helps close-ups.

Claude Code alternatives, priced per finished task: OpenCode with DeepSeek cost about a cent, GLM-5.3 cost what Sonnet did, and the host set the bill.

An AI video detector can only guess. The label inside the file is proof, but every re-save I tried stripped it. Plus the visual tells that still work.

AI images from OpenAI and Google carry a signed C2PA label that says a model made them. I read the labels, then tried five everyday edits. None kept it.

ChatGPT vs Claude on eight everyday tasks: GPT-6 Sol and Sonnet 5.5 answered about equally well, so the $20 choice comes down to what each plan bundles.

OpenAI API pricing for GPT-6.1 Sol, Luna and Astra, and what a real request costs after hidden reasoning, cache-write fees, long context and the tokenizer.

Cursor now bills Claude at API price. A heavy month of agent work comes to about $11,900 there, against a $200 Claude Max plan with a cap. Where Cursor fits.

Kling AI pricing in dollars: what each plan costs per second of Kling 3.0, when the API is cheaper, and how rerolls and expiring credits change the answer.

Opus vs Sonnet in Claude Code on eight coding tasks: every setting passed, so cost and time per task decide. Effort level moved the bill more than the model.
Codex vs Claude Code on the same 8 coding tasks: every run passed, Claude Code was faster, and Codex cost a fifth as much per task at API prices.

What is OpenRouter? One API and one bill for 400+ AI models from dozens of hosts. What it charges, why the host matters, and what the free models really give.

Where to check Codex usage limits in ChatGPT and the CLI, and what 1% of a Plus week buys at API prices, measured from six months of my own Codex logs.
Claude Code pricing runs $20 to $200 a month. I measured one Max 20x window at about $300 of Opus 5.5 work at API prices, and a week at about ten windows.

Compare social media API costs for LurkAPI, ScrapeCreators, TwitterAPI.io, and X, with billing units, prepaid pack prices, and practical workload examples.

I trained the same two faces on six base models (Ideogram, Flux.1 Dev, Flux.2, Klein, Krea, Z-Image) to find the best base model for character LoRA training in 2026.

The best free AI tools for marketing in 2026, sorted by job: copywriting, research, design, ad creative, social scheduling, motion, and AI-answer visibility.

Spotify keeps raising prices while lossless lags. We compared the best Spotify alternatives on price, sound quality, catalog, and free tiers to find your fit.

Privacy pushes and a RAM-hungry app have people leaving Discord. We compared the best alternatives for teams, communities, privacy, and gaming voice in 2026.

After Effects is powerful, pricey, and slow to learn. We tested the top alternatives on price, speed, and real output to find which one actually fits.

Leaving Character.AI? We compared the top alternatives on memory, message limits, character libraries, and content filters to find the best fit in 2026.

AI answers now drive discovery. We compared the best LLM visibility tools on what they track, what they cost, and which one actually changes what AI says.

The US ordered Anthropic to cut off Fable 5 for foreign nationals, so it pulled its most powerful model offline worldwide. What happened, and why it matters.

We tested the top Facebook ad creative tools, from Meta Ad Library research to AI-generated scroll-stoppers. Here's what actually moves the needle.

AI-generated UGC video ads are the new performance creative. We tested the top tools side-by-side on real scripts. Here's how they compare.

We tested the top AI ad copy generators on real campaigns. Compare features, pricing, and which ones actually write copy that converts.

We tested the top AI headshot generators on real selfies. Compare quality, turnaround time, and pricing to find the best LinkedIn headshot tool.

From 4K product photos to 10x portrait enlargements, we tested the top AI image upscalers on real images. Here's how they compare.

We tested the top AI background removers on hair, fur, and complex edges. Here's which ones deliver clean cutouts and which fall apart.

We tested the top AI ad generators head-to-head. Compare features, pricing, and real output quality to find the right tool for your campaigns.

From background removal to full scene generation, we compared the top AI image editors on real tasks. Here's what actually delivers.

Old photos don't have to stay old. We tested AI restoration tools on scratched, faded, and damaged images to find what actually works.